Resources · Blog
The NexNodo blog
Insights on cloud infrastructure, GPU compute, Kubernetes, AI ecosystems, and modern data center business models. Platform updates, deployment guides and engineering write-ups from the team building the infrastructure.
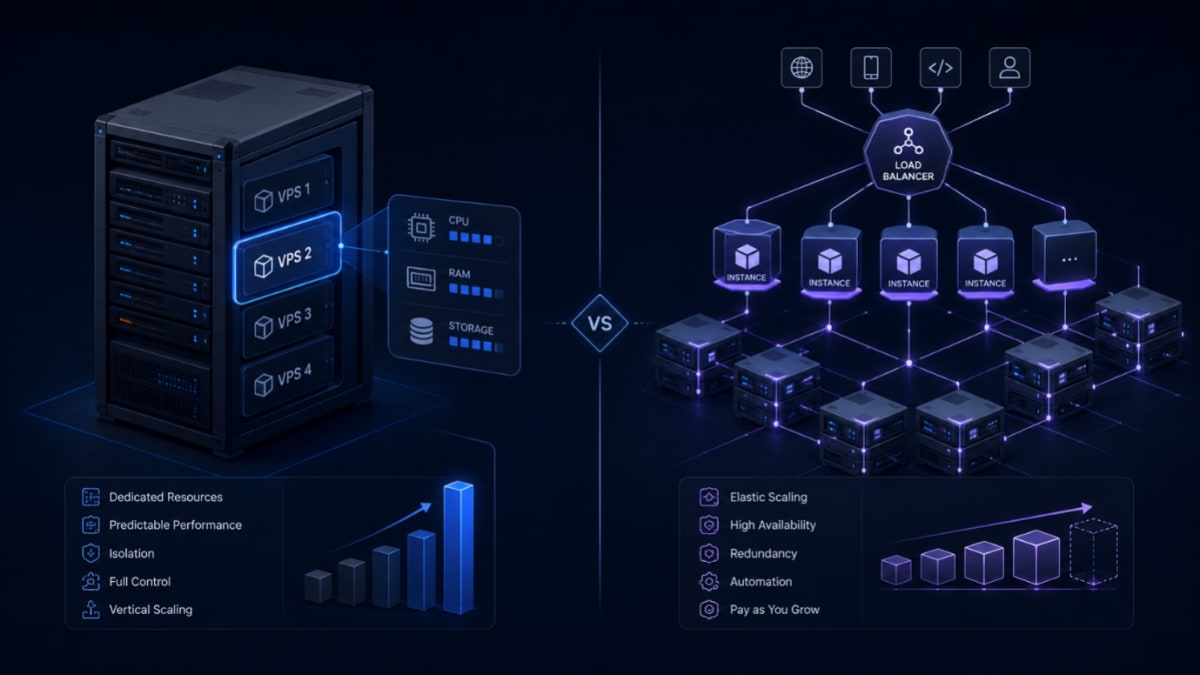 VPS vs Cloud Hosting: What’s the Difference and Which Should You Choose? Cloud Infrastructure 9 min read
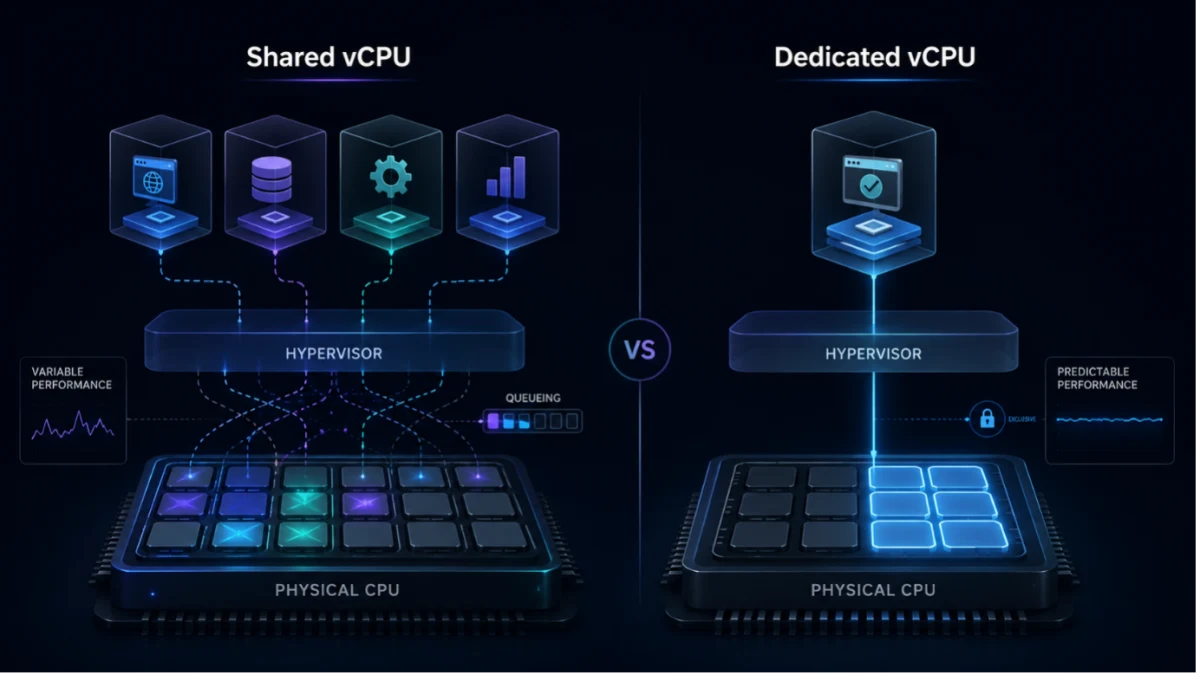 Dedicated vCPU vs Shared vCPU: Performance, Cost, and When to Use Each Cloud Infrastructure 11 min read
 Cloud Providers for Europe Compared 2026: VPS, Kubernetes & Pricing Cloud Infrastructure 14 min read
- Running JupyterHub for AI Teams: Shared Notebooks Without Shared Chaos AI Infrastructure 5 min read
Featured Articles
Product news and engineering write-ups from the NexNodo team.
VPS vs Cloud Hosting: What’s the Difference and Which Should You Choose?
Compare VPS vs cloud hosting across performance, scalability, reliability, pricing and management to choose the right infrastructure for your workload.
Dedicated vCPU vs Shared vCPU: Performance, Cost, and When to Use Each
Compare dedicated vCPU vs shared vCPU for performance, cost, CPU contention, steal time and real workloads. Learn when each VPS option makes sense.
Cloud Providers for Europe Compared 2026: VPS, Kubernetes & Pricing
Compare leading European cloud providers for VPS, Kubernetes, pricing, billing and infrastructure, including Hetzner, Contabo, DigitalOcean, Vultr, Scaleway and NexNodo.
Running JupyterHub for AI Teams: Shared Notebooks Without Shared Chaos
Individual notebooks on individual laptops do not scale past one person. JupyterHub gives a team a shared, GPU-backed notebook environment without the usual mess.
Kafka vs. Redpanda for Real-Time Data Pipelines
Redpanda promises Kafka-compatible streaming without the JVM or ZooKeeper. Here is what actually changes in production.
Building AI Coding Assistants with OpenHands and Self-Hosted LLMs
Autonomous coding agents can read a codebase, write patches, and run tests — but sending your source code to a third-party API is a non-starter for many teams.
MLOps on Kubernetes: Managing the Model Lifecycle with MLflow and Kubeflow
Training a model is the easy part. Tracking experiments, versioning artifacts, and reproducing results reliably is where most AI teams struggle.
Vector Database Showdown: Qdrant vs. Milvus vs. Weaviate for Production RAG
Three open-source vector databases dominate production RAG deployments. Here is how they actually differ once you get past the marketing pages.
Monitoring AI Applications with Langfuse, Prometheus, and Grafana
LLM applications need two layers of observability — application-level tracing and infrastructure-level metrics — and neither one substitutes for the other.
Building a Data Lakehouse on Kubernetes with Spark, Trino, and MinIO
A lakehouse combines the flexibility of a data lake with the query performance of a warehouse — and Kubernetes makes the whole stack portable.
Designing Multi-Agent AI Systems for the Enterprise
A single AI agent works for one team. Coordinating specialized agents across departments on shared infrastructure requires a different architecture.
Automating Document Workflows with n8n and Private AI
Combining n8n with a private LLM turns document-heavy manual processes — invoices, contracts, onboarding forms — into automated pipelines.
Choosing Between Ollama and vLLM
Ollama and vLLM both serve open-source language models, but they are built for very different scales and use cases. Here is how to pick the right one.
Build a Private ChatGPT Without OpenAI
How organizations are deploying private AI assistants on their own infrastructure — with full data ownership and no per-token charges.
How to Build AI Agents for Internal Teams
AI agents go beyond answering questions — they can execute workflows, search internal knowledge, and connect to business systems.
Enterprise RAG Explained: The Fastest Way to Search Company Knowledge
RAG (Retrieval-Augmented Generation) enables meaning-based search across company knowledge — without the latency or cost of a GPU.
Building AI-Powered Customer Support
AI can dramatically reduce first response times and ticket volume while improving consistency across your support team.
Why More AI Startups Are Switching to vLLM
As request volumes grow, inference performance becomes critical. vLLM has become the standard serving framework for production AI APIs.
How Data Centers Can Operate Like Hyperscalers
Modern cloud business models for infrastructure providers.
Building AI Infrastructure with GPU Kubernetes and Open Source Services
Deploy scalable AI environments using Kubernetes, GPU compute, and deployable services.
The Rise of MCP Servers in AI Ecosystems
How Model Context Protocol servers are connecting AI systems to real-world infrastructure.
Kubernetes-Native Application Deployment: Best Practices
Streamline your deployment workflows with the NexNodo App Catalog.
GPU Infrastructure Economics: Cost Optimization Strategies
Maximize ROI on GPU deployments for AI and ML workloads.
From Colocation to Cloud Platform: A Data Center Transformation Guide
Step-by-step guide for infrastructure providers transitioning to cloud services.